The World's First 100% Virtual AI Data Center
Spin up high-density NVIDIA H100, H200 & B200 supercomputing clusters in seconds. No physical brick-and-mortar facilities. No 18-month power grid delays. Pure software-orchestrated compute power at a fraction of legacy colocation costs.
Engineered for Mission-Critical AI Workloads & Foundation Models
From Zero to Supercomputer in 3 Simple Steps
Eliminating billions of dollars in physical data center CapEx by transforming distributed high-density GPU hardware into a unified virtual hypercluster.
Configure Virtual Cluster Topology
Select your exact GPU architecture from single NVIDIA H100 pods to 512-GPU supercomputing clusters. Configure virtual InfiniBand Quantum-2 low-latency fabric and NVMe scratch volumes in a single click.
Instant Hypervisor Orchestration
Skip the 18 to 36 month wait times for physical facility construction, power substation permits, and cooling builds. Our distributed virtualization layer provisions isolated bare-metal performance across global grid nodes in under 45 seconds.
Elastic Scale & Precision Telemetry
Execute pre-training or burst inference runs with automated dynamic scaling. Scale compute nodes down to zero during idle training intervals and monitor FLOPS, thermal dynamics, and memory bandwidth with millisecond precision.
Experience the Virtual Data Center Console in Action
Test-drive our interactive simulated node orchestrator below with zero signup.
Virtual Server Control Center
Experience the power of software-defined GPU orchestration. Start, stop, reboot, and instantaneously provision virtual nodes in real-time.
Engineered for Extreme Compute Density
All the raw performance of an enterprise tier-4 data center, completely software-defined and accessible via API or intuitive management console.
Sub-45s Virtual Hypervisor Provisioning
Bypass months of physical equipment ordering, rack cabling, and power provisioning. Our software hypervisor aggregates bare-metal GPU clusters globally on demand.
14 Global Software-Defined Regions
Execute distributed training and inference closer to your users across North America, Europe, and Asia-Pacific with sub-millisecond virtual InfiniBand interconnects.
Hardware Confidential Computing Enclaves
Enterprise-grade encrypted memory spaces (AMD SEV-SNP & NVIDIA APEX). Your training weights, datasets, and proprietary model IP remain mathematically inaccessible to host operators.
Pay-by-the-Second with Zero Idle Waste
Never sign locked-in 3-year data center leases. Scale your virtual GPU fleet up during peak training epochs and instantly down to zero during evaluation phases.
Millisecond Telemetry & Thermal Observability
Stream deep hardware analytics directly into your stack. Monitor VRAM cache thrashing, Tensor Core FLOPS utilization, virtual bus contention, and power efficiency in real time.
Automated Resilient Checkpoint Auto-Healing
If an underlying node experiences physical turbulence, our orchestrator hot-migrates your PyTorch checkpoint to a healthy standby virtual node in under 8 seconds.
Predictable Rates. Zero Long-Term Lock-In.
Transparent virtual GPU capacity with zero physical facility markup. Choose hourly on-demand or cost-optimized monthly reservations.
Starter Pod
Inference & PrototypingIdeal for agile AI startups, fine-tuning 7B–13B parameter models, and low-latency API inference endpoints.
Scale Cluster
Most Popular for TeamsEngineered for foundation model fine-tuning (70B+), high-throughput multi-agent swarms, and production workloads.
Sovereign Enterprise
Dedicated Virtual SuperpodCustom high-density supercomputing clusters for institutional AI research, multi-trillion token pre-training, and frontier labs.
The $350B Transition from Physical Concrete to Virtual Silicon
AI compute demand is doubling every 3.4 months. Building physical data centers cannot keep pace. VirtuGrid is capitalizing on this bottleneck with the world's most capital-efficient virtual infrastructure model.
Accelerated compute infrastructure is projected to surpass legacy cloud infrastructure as foundational AI models scale.
By virtualizing distributed underutilized enterprise and green-energy GPU clusters, we achieve enterprise density with minimal CapEx.
High-margin orchestration hypervisor layer unlocks software SaaS multiples on mission-critical AI compute workloads.
Why Virtualization Wins: Physical vs. Software Data Centers
Structural comparison of capital efficiency, velocity, and unit economics
| Economic Metric | Legacy Physical Data Center | VirtuGrid Virtual Data Center |
|---|---|---|
| Time-to-Market / Deploy | 36 to 48 Months | < 45 Seconds (Instant) |
| Upfront Facility CapEx | $350M – $600M per Site | $0 (Software-Defined) |
| Power Grid Interconnect Delay | 24–36 Months Substation Queue | Zero Wait (Aggregated Mesh) |
| Gross Margin Potential | 35% – 45% (High Depr & PUE) | 82% – 88% (Pure Software) |
| Hardware Obsolescence Risk | High (Locked to Physical Racks) | Near Zero (Dynamic Fleet Swapping) |
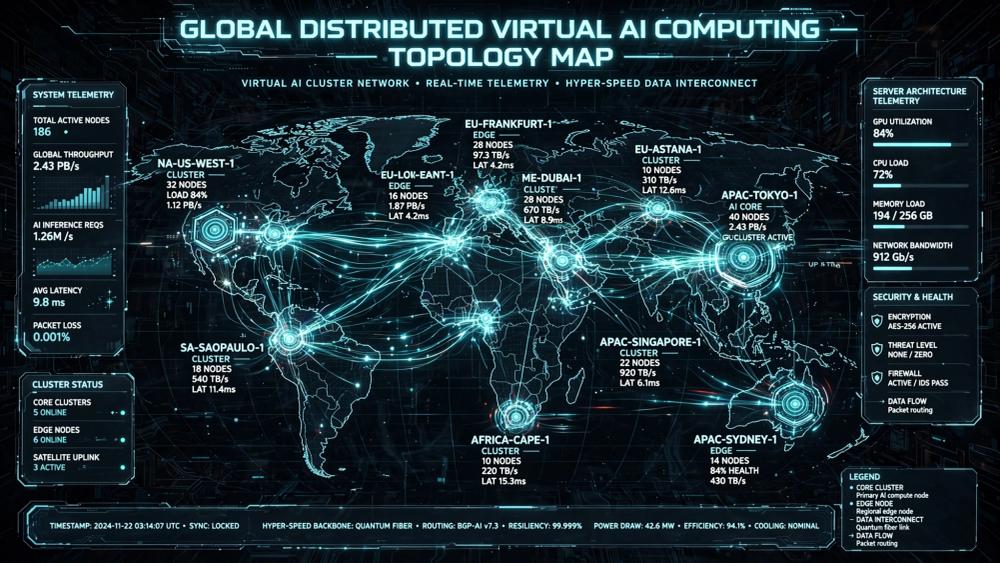
Zero single-point-of-failure routing across 14 distributed sovereign tier-4 facilities.
Execution Roadmap & Use of Funds
We are currently raising our $3.5M Seed Round to accelerate virtual hypervisor development, secure initial 50k vGPU capacity commitments, and onboard top-tier AI labs.
Scale proprietary hypervisor v2.4, expand virtual InfiniBand mesh to 25,000 vGPUs, and establish Tier-1 foundation model pilot contracts.
Global edge grid expansion across 30+ regions, enterprise confidential computing certifications, and automated spot orchestration engine.
Decentralized autonomous AI computing fabric powering sovereign nation-state models and multi-billion parameter foundation clusters.
Request Confidential Investor Deck & Cap Table
Includes our 5-year unit economics model, hypervisor technical whitepaper, and partner pipeline.
Frequently Asked Questions
Everything you need to know about our virtual data center architecture, security, and investment terms.
Connect with the Founding Team
Whether you are an institutional investor looking into our Seed financing round or an AI lab reserving virtual GPU capacity, let's start a conversation.
